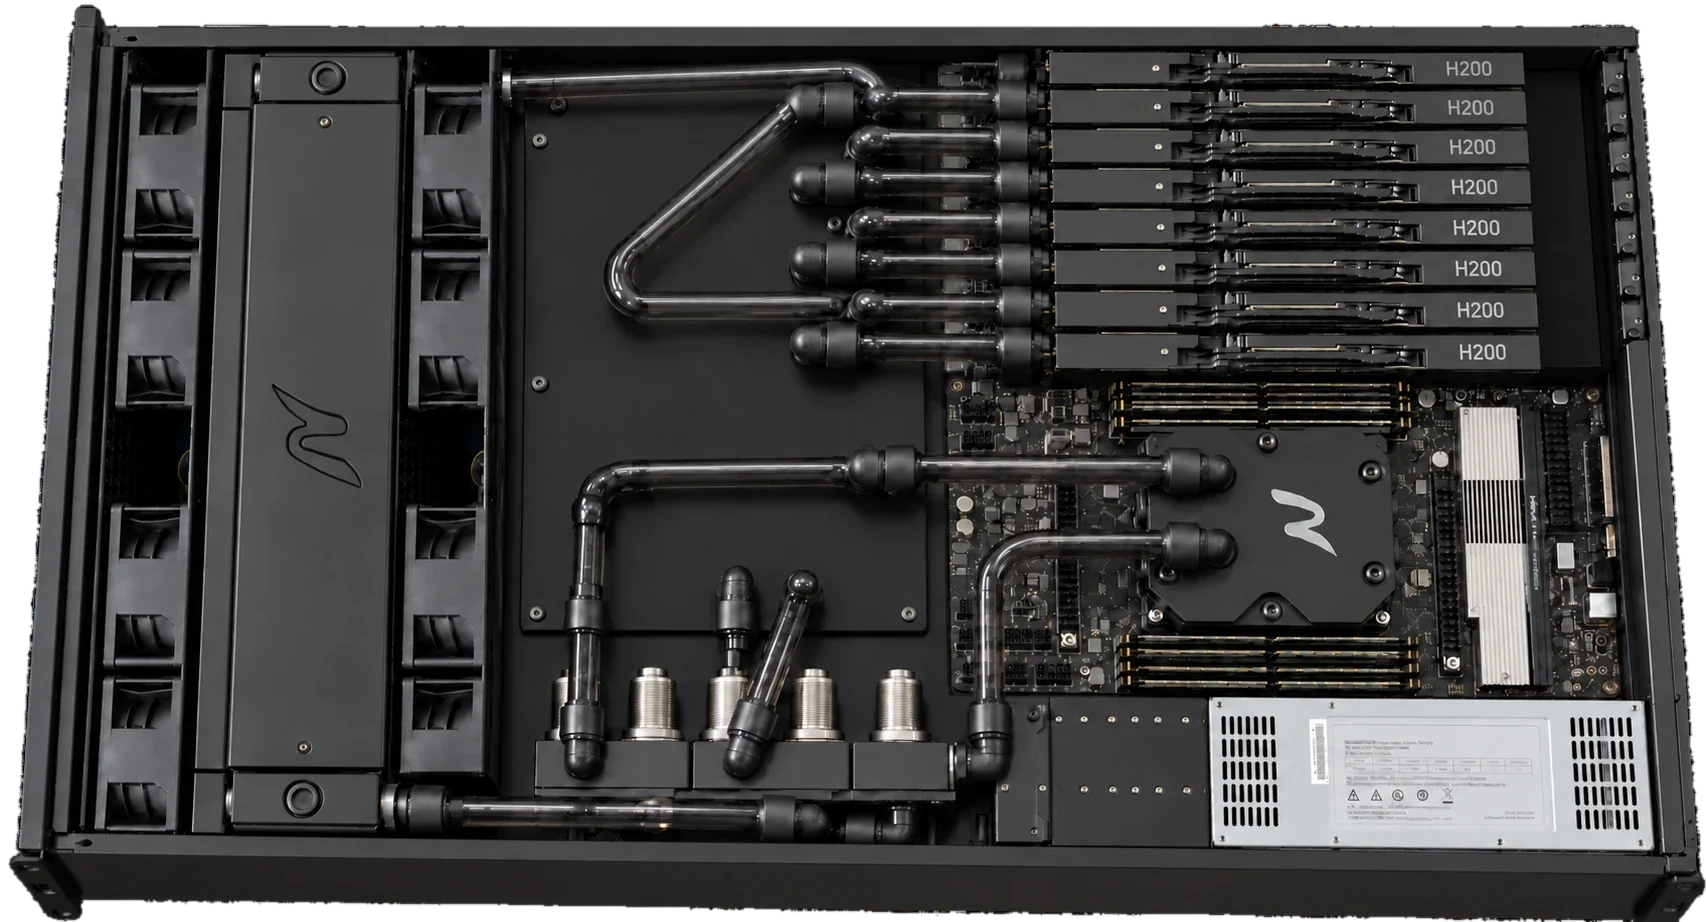
The Nova range: liquid-cooled 8-GPU servers for AI inference and training. Built by Renda, cooled end to end by Nexalus, benchmarked before they ship.
Most teams don't want a spec sheet, they want AI that works. Pick the server for the job, or take both as a rack.

Speed and output for serving models to users and applications.

Memory-first, for training, fine-tuning and the largest models.
The complete AI system, liquid-cooled as one, delivered and benchmarked.
All eight GPUs flat out for an hour, 175 back-to-back runs. Throughput held at ~54,000 tokens a second and the hottest GPU stayed at 80 °C or below.
Every card averaged more than 6,600 tokens a second across the hour.
Replay of measured data from the Nova 8 Inference development build.1 See the full benchmark →
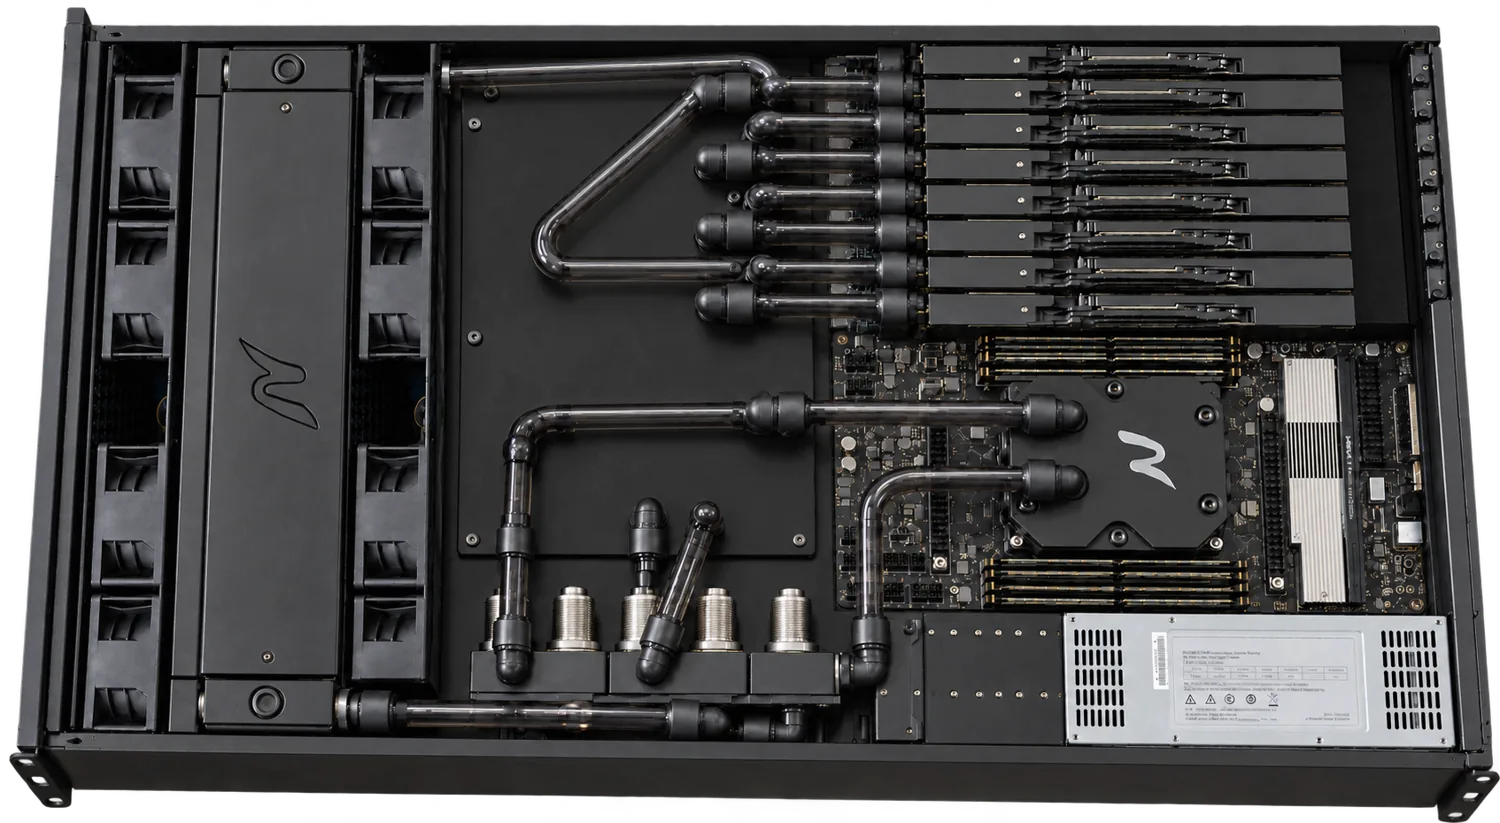
Every GPU in a Nova server sits on a Nexalus liquid loop. Heat leaves at the chip, so the silicon holds its boost clocks, the server spends less power on fans, and the heat comes out as hot water instead of hot air.
Cooler GPUs hold higher clocks under sustained load: +20% tokens from the same eight GPUs.
Power goes into inference, not into moving air: 8.6 tokens per watt vs 7.0.
Single-slot liquid blocks put eight full-power GPUs in one 4U chassis.
Up to 60 °C water out. Reject it with a dry cooler or heat buildings with it.
Run models on your own premises. Your data never leaves the building.
The same liquid-cooled GPU platform for simulation, rendering and VFX.
Liquid-cooled GPU and CPU hardware on hand, plus a live remote session with the Nova 8 test server. Book a meeting.
Nova 8 on show with our cooling partners. Come and see the loop up close.
Book a two-hour remote session in a fresh, isolated environment. See your own tokens per second before you commit.