Home / Products / Nova 8 Training
In development · early access open

Nova 8 Training.
Memory first.

Cooled by Nexalus
Eight NVIDIA H200 NVL GPUs with 1.1 TB of HBM3e between them, on the same Nexalus liquid loop as Nova 8 Inference. Built for training, fine-tuning and serving the largest models on your own premises.
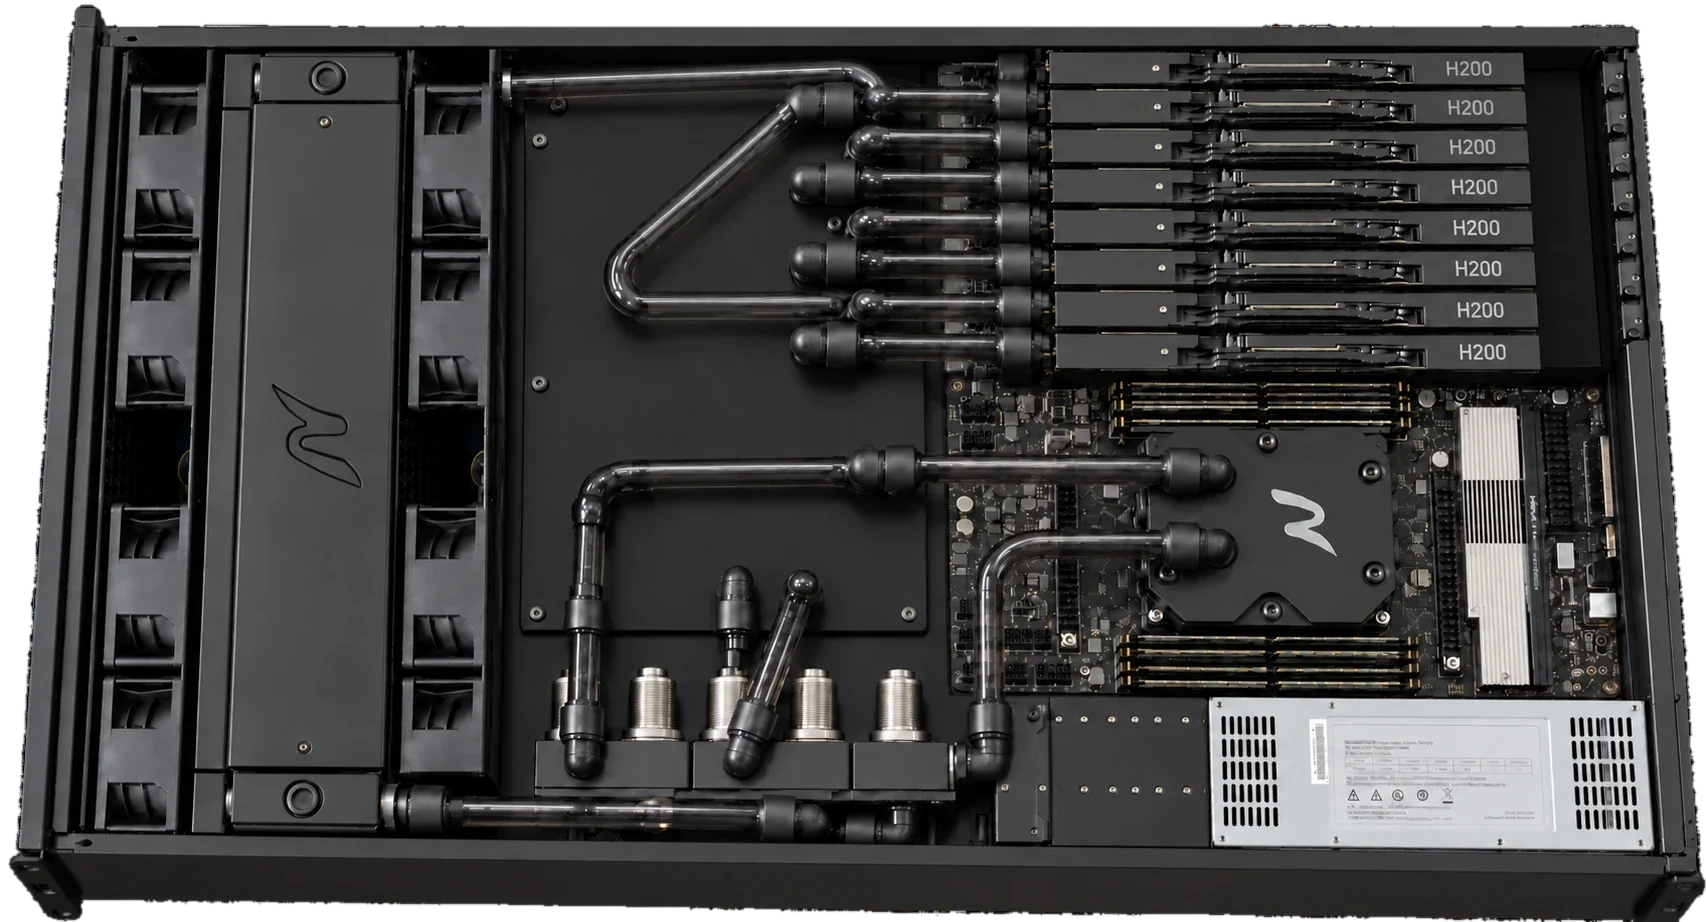
Nova 8 Training, top view: eight H200 GPUs and the CPU on one Nexalus loop
1,128 GBHBM3e GPU memory per server4
GPU memory
1,128GB HBM3e
8 × 141 GB H200 NVL. Room for the largest open models and long contexts.4
Memory bandwidth
4.8TB/s per GPU
HBM3e keeps the tensor cores fed during training. 2.7× the RTX PRO 6000.4
GPU-to-GPU
900GB/s NVLink
NVLink bridges link GPUs for fast gradient exchange.4
Training or inference?

Two jobs. Two servers. One loop.

Cooled by Nexalus

Training is learning: the model reads huge amounts of data and adjusts billions of weights, so memory and bandwidth matter most. Inference is answering: the model serves users, so tokens per second and per watt matter most.

Serving models to users and apps

Nova 8 Inference

8 × RTX PRO 6000 Blackwell

  • Up to 55,000 tokens / s measured
  • 8.6 tokens per watt
  • 768 GB GDDR7
  • Chatbots, copilots, RAG, agents, batch inference

Nova 8 Inference

Training, fine-tuning, the largest models

Nova 8 Training

8 × H200 NVL

  • 1,128 GB HBM3e, 4.8 TB/s per GPU
  • NVLink-bridged GPUs
  • Fine-tuning on private data, domain models
  • Serving very large models and long contexts

Join early access

Nova 8 InferenceNova 8 Training
GPUNVIDIA RTX PRO 6000 BlackwellNVIDIA H200 NVL
Memory per GPU96 GB GDDR7141 GB HBM3e
Memory per server768 GB1,128 GB
Bandwidth per GPU1.8 TB/s4.8 TB/s
GPU interconnectPCIe Gen5NVLink bridges, up to 900 GB/s
Best atTokens per watt and per boxTraining, fine-tuning, very large models
StatusTaking pre-ordersIn development · early access
Nova 8 Training figures are targets based on NVIDIA's published H200 NVL specifications.4
What you can do with it

Your models, trained on your data, in your building.

Cooled by Nexalus

Fine-tune on private data

Adapt open models to your documents, code and customers without sending data to a cloud.

Train domain models

Continued pre-training for legal, medical, financial or engineering language.

Serve the largest models

1.1 TB of HBM3e holds very large open models and long contexts on one server.

Embeddings and RAG at scale

Re-index millions of documents quickly so retrieval stays fresh.

Why liquid for training

Training runs for days. The cooling has to hold.

Cooled by Nexalus

A training job keeps every GPU at full power for days or weeks. Air-cooled servers throttle as the hall warms up; a liquid loop holds the chips at a steady temperature, so the last epoch runs as fast as the first.

  • Same Nexalus loop proven on Nova 8 Inference: one hour at full load, no card above 80 °C
  • Redundant pumps and fans: a single failure doesn't stop the job
  • Steadier temperatures mean less thermal cycling wear on the hardware
  • Up to 60 °C water out for heat reuse5
Nova 8 Training: eight H200 GPUs on the Nexalus liquid loop
Target specification

Nova 8 Training

Cooled by Nexalus
GPUs8 × NVIDIA H200 NVL, 141 GB HBM3e each, up to 600 W
GPU memory1,128 GB total · 4.8 TB/s per GPU
GPU interconnectNVLink bridges (2- or 4-way), up to 900 GB/s GPU-to-GPU · PCIe Gen5 to host
CPU & memoryAMD EPYC · large DDR5 capacity for data staging
NetworkingHigh-speed NICs for multi-node training and storage (configurable)
CoolingNexalus direct liquid cooling on every GPU and the CPU · redundant pumps and fans · optional rear quick-connects for heat export
Form factorRack-mount, standard 19-inch
StatusIn development · early-access list open
Target specification for a product in development. Specification, availability and appearance will change.4
Don't take our numbers

Be first in line for Nova 8 Training.

Join early access for engineering samples, or test your inference workload on Nova 8 today.