Home / Products / Nova 8 Inference
Taking pre-orders

Nova 8 Inference.
55,000 tokens a second.

Cooled by Nexalus

Eight full-power NVIDIA RTX PRO 6000 Blackwell GPUs in one 4U server, liquid-cooled end to end. Built to serve models at scale, on your premises or in your data centre.

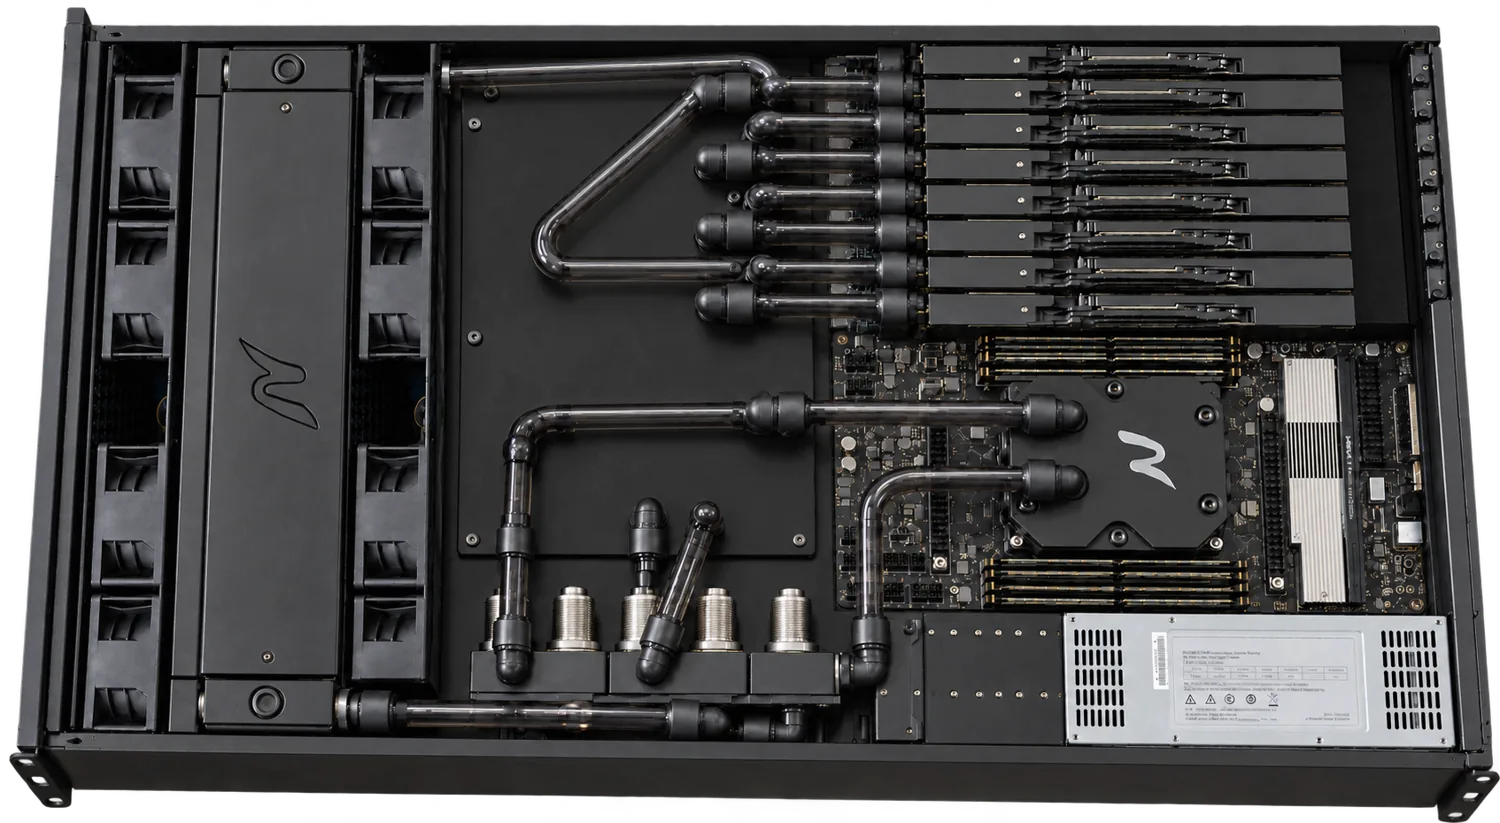
Nova 8 Inference, top view
Replay · 1-hour run54,968tokens / second
Throughput
55,000tok/s
Up to 55,000 tokens a second from one 4U server, Llama 3.3 70B.1
Versus air-cooled
+20%tokens
More tokens than a leading tier-1 air-cooled 8-GPU server, same GPUs.2
Efficiency
+22%per watt
8.6 tokens per watt vs 7.0. Less power for every token served.3
Performance you can hold

An hour at full load, every GPU.

Cooled by Nexalus

175 back-to-back benchmark runs on all eight GPUs. Throughput held at ~54,000 tokens a second and no card went above 80 °C. Press pause to inspect any run.

Server throughput Replay

54,968 tokens / s
Run 1 / 175Elapsed 0 minHour average 53,984Hottest GPU 65 °C
5 Oct 2026 · 12:28–13:26 UTC

Per GPU, this run

Every card averaged more than 6,600 tokens a second across the hour.

Replay of measured data.1 At launch this panel streams live from the test server.

Tokens per watt

Every watt makes more tokens.

Cooled by Nexalus

Air cooling spends power moving air. Nova 8 takes heat off the silicon into liquid, so more of every kilowatt goes into inference.

Tokens / second per watt · 8-GPU server
Nova 8 Inference, cooled by Nexalus8.6
Tier-1 air-cooled, same RTX PRO 6000 GPUs7.0
8 × H200 air-cooled reference5.7
+22% tokens per watt. Run the same AI service on less power, or more AI on the power you already have.3
Where the energy goes
Grid power~6.4 kW Nova 88 GPUs, one loopliquid at the chip Tokens55k / second Hot waterup to 60 °C
31M

tokens per kWh with Nova 8

25M

tokens per kWh, air-cooled reference

Inside Nova 8 Inference

A complete thermal system, not a bolt-on.

Cooled by Nexalus

Every component on the loop is chosen and tuned to work together. Each adds a few percent; stacked, they let eight 600 W GPUs run flat out in 4U.

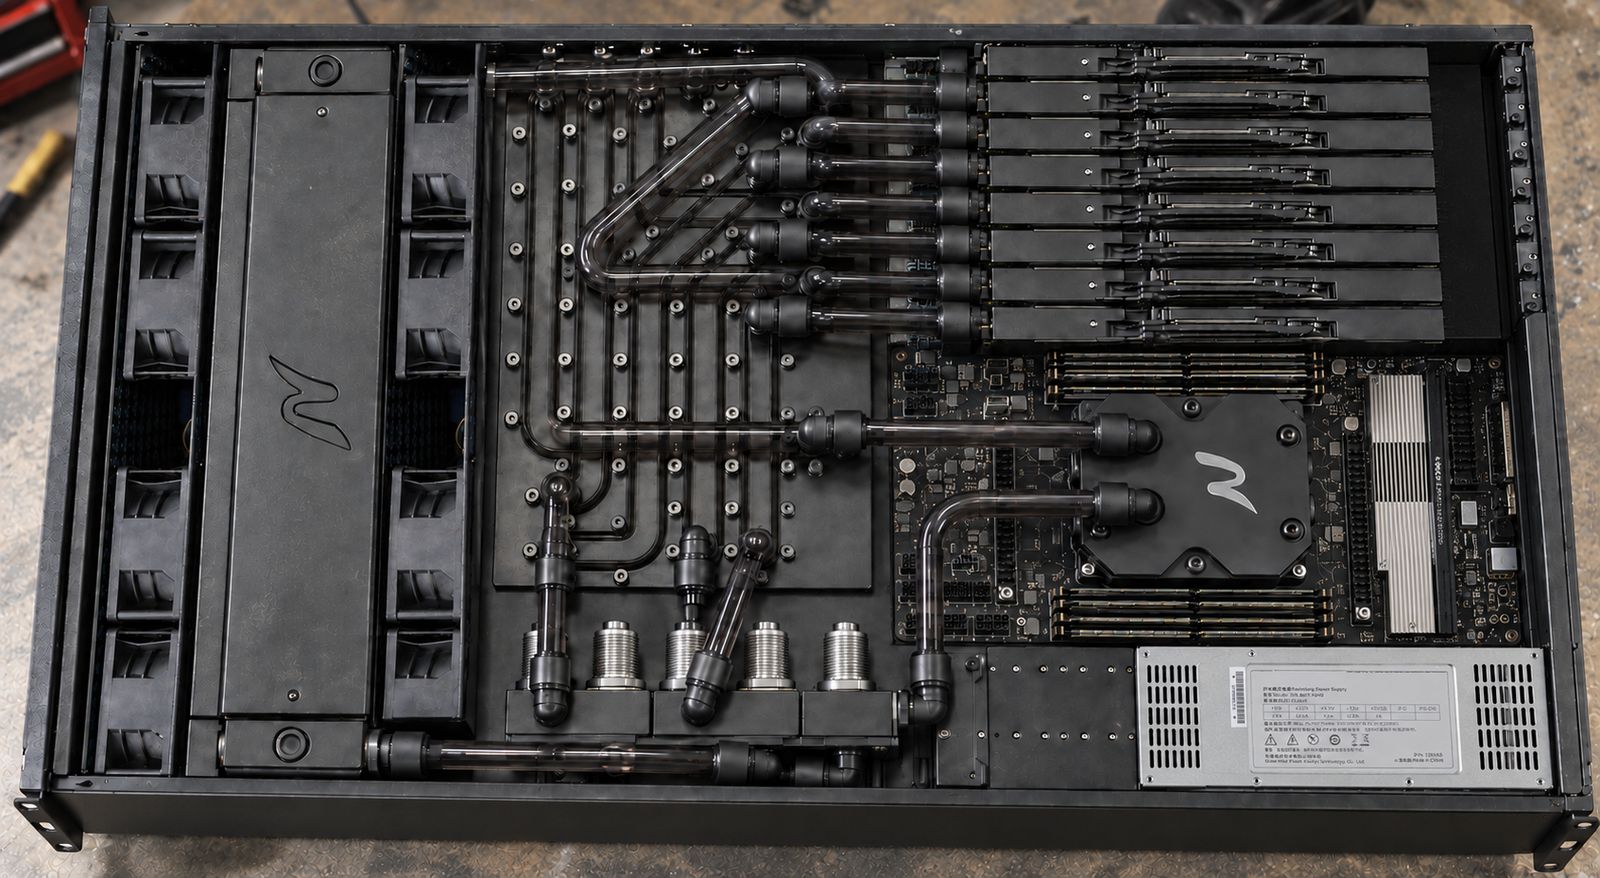
Nova 8 top-down: liquid loop, eight GPUs, CPU block, pumps and radiator
Specifications

Nova 8 Inference

Cooled by Nexalus
GPUs8 × NVIDIA RTX PRO 6000 Blackwell, 96 GB GDDR7 with ECC each, full 600 W, no de-rating
GPU memory768 GB total · 1.8 TB/s per GPU
CPU & memoryAMD EPYC, single socket · up to 2 TB DDR5
Storage8 × U.2 PCIe Gen5 NVMe
Power4 × 3 kW 80 PLUS Titanium, 2+2 redundant · ~6.4 kW typical at full load (estimate)
CoolingDirect liquid cooling on every GPU and the CPU · jet-impingement cold plates · 10 aerospace-grade micropumps in 5 redundant loops · 16 fans · balanced flow · medical-grade tubing
Form factor4U, standard 19-inch rack · optional rear quick-connects for heat export
SoftwareLinux with NVIDIA drivers and TensorRT-LLM, pre-installed and benchmarked · compatible with vLLM, NVIDIA NIM and other CUDA inference stacks
MeasuredUp to 55,000 tokens/s · 53,984 tokens/s one-hour average · Llama 3.3 70B NVFP41
Also available7-GPU configuration for single-phase power
Preliminary specification for a pre-production product. Specification and appearance may change.
Fleet calculator

What Nova 8 does to your running costs.

Cooled by Nexalus

Set your fleet size and energy price. We compare Nova 8 Inference with an air-cooled 8-GPU fleet serving the same tokens.

0

tokens served per year

0

less electricity per year, same tokens

0

energy cost saved per year

0

CO₂ avoided per year

0

air-cooled servers needed for the same output

0

heat available for reuse per year

Estimate. Uses the one-hour average (53,984 tokens/s), an estimated 6.4 kW per server, the published air-cooled reference (45,527 tokens/s, 7.03 tokens/s per W) and 90% heat capture (design value).3

Inference or training?

Need more memory than speed?

Cooled by Nexalus

RTX PRO 6000 Blackwell gives the most tokens per watt for serving models. For training, fine-tuning and the very largest models, Nova 8 Training brings H200 memory.

Compare with Nova 8 Training

Don't take our numbers

Run your model on a live Nova 8.

Book a two-hour remote session in a fresh, isolated environment. See your own tokens per second before you commit.